Odyssey has launched Odyssey 3, a foundational world model that transforms a textual description into an explorable environment in real time, in first or third person, with independent camera movement. The difference from video generators is substantial: rather than producing a clip to watch, the system continuously predicts what happens next as the user moves, and so the world reacts to their actions. It is even possible to introduce an event whilst the simulation is in progress. The research preview has been available free of charge in the browser since 8 October, whilst the model weights are not publicly available.
Technically, it is an autoregressive diffusion transformer with 14 billion parameters, which generates frames sequentially by conditioning them on previous frames and received actions. Training utilises teacher forcing and causal masking, so the model does not look ahead. To achieve interactive speed, a post-training phase involving distribution matching and adversarial distillation produces a distilled variant with just a few diffusion steps, designed for live interaction, whilst the demo uses the Flash variant. The resolution is 832 by 480 pixels, rising to 1280 by 720 in the Pro version. The data includes internet videos with annotated events, gaming sessions with time-aligned keyboard and mouse inputs, and simulated interactions between rigid bodies.
In terms of performance, Odyssey claims a score of 66.1 on Physics IQ Verified for the Pro variant in the video-to-video comparison, and first place in three out of four categories on the WorldMark benchmark. These figures should be interpreted with caution: the 66.1 corresponds to the best result out of eight attempts, whilst the average across four runs drops to 63.37, and the WorldMark assessment was conducted by the company itself – which, when using real-world scenes, ranks only third. No independent tests have yet confirmed these results.
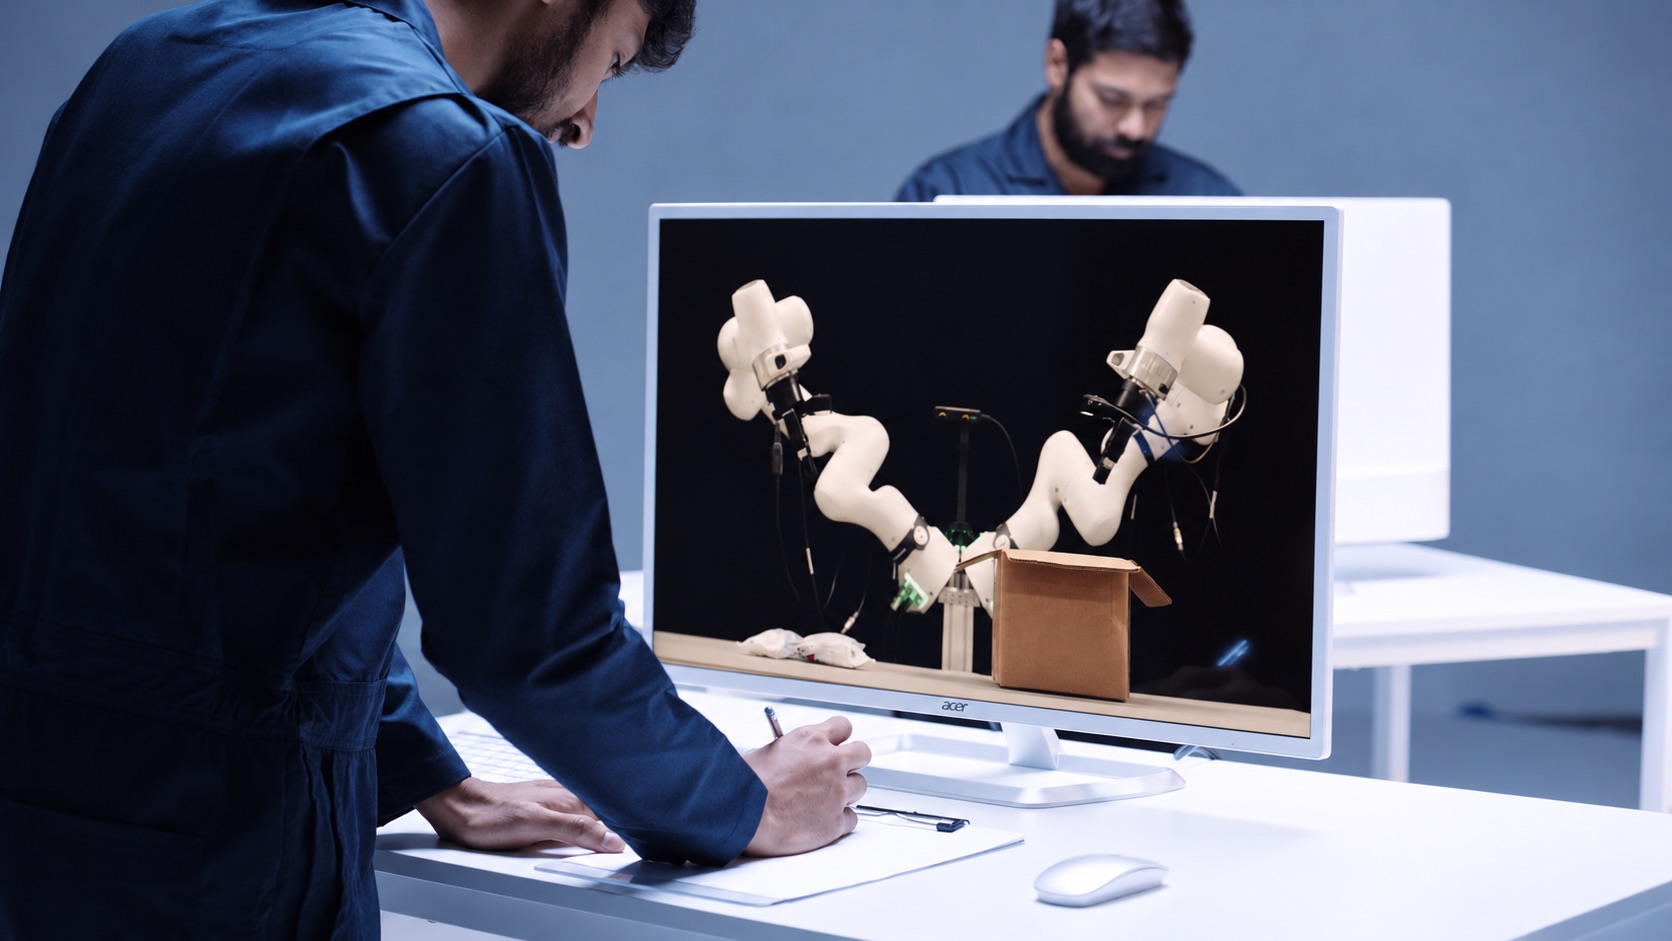
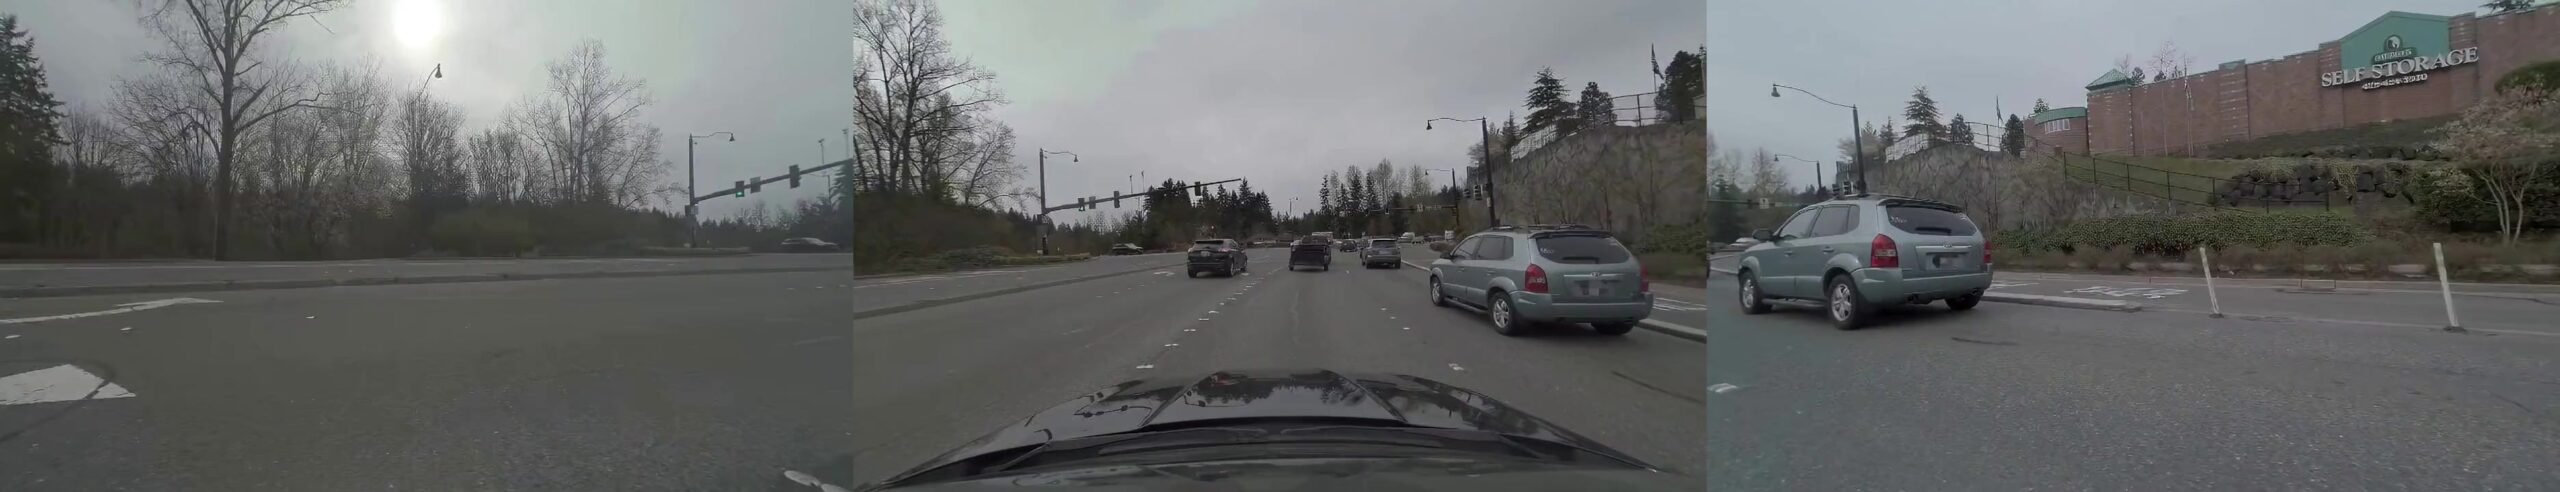
The stated aim is not entertainment but machine training. With just a few dozen hours of demonstrations, the model completed manipulation tasks using robotic arms, recovering from errors not present in the data, such as a missed grip. Flexion has built three control policies for humanoids on Odyssey that outperformed the tested baselines when lighting conditions changed, whilst a driving policy trained on approximately 20 hours of data, with the backbone frozen, drove a car on real roads in India. In a preliminary experiment, a checkpoint generated the combined views from the three front-facing cameras of a driving dataset after just 100 training steps.
Anyone wishing to try it out can do so straight away: the free demo is available in your browser at experience.odyssey.systems; details can be found on the official Odyssey website, and developers can request access to the APIs. Oliver Cameron, CEO and former vice-president of product at Cruise, describes it as ‘a major step towards a single intelligence capable of understanding and operating in the world around us’. The point is not how wonderful today’s world is, but that, for the first time, the world responds to those who observe it.